An AI pilot can look inexpensive right up until it becomes useful.
The demo works. People begin using it. More documents are indexed, more requests are sent, and the most powerful model is called for tasks that never needed it. Then the first production invoice arrives, and the project that looked efficient suddenly starts behaving like a tap left open.
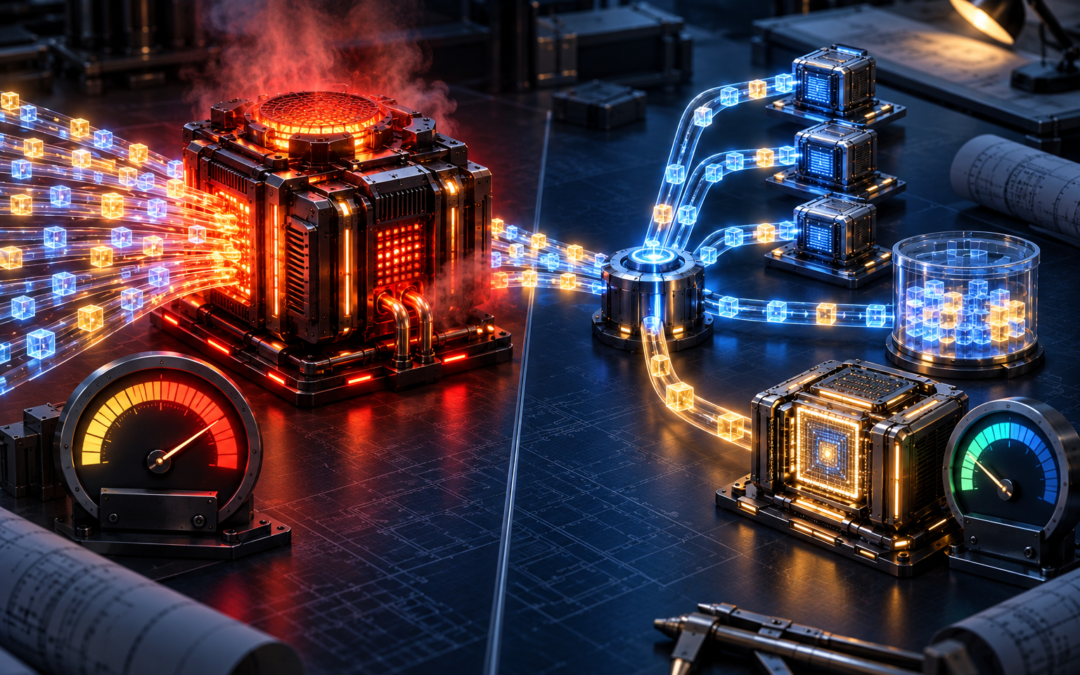
AI cost optimization is therefore not a finance problem to solve after deployment. It is an enterprise AI architecture decision that begins before the first model is selected. Every request, token, retrieval step, retry and infrastructure choice has a cost. If those choices remain invisible, the bill becomes unpredictable. If they are designed deliberately, AI can scale without turning into an expense nobody can explain.
The objective is not to make AI cheap at any price. It is to spend computing power where it creates real value and avoid paying for intelligence the task does not need. In practice, that discipline rests on five architectural decisions.
Do Not Hire a Nuclear Physicist to Correct an Email
One of the most expensive habits in AI is sending every request to the most powerful model available. It is like hiring a nuclear physicist to correct spelling mistakes in an email. The expert can certainly do it, but the task does not justify the cost.
A better architecture uses model routing. Think of it as an experienced receptionist who listens to each request before deciding where it should go. A complex question involving several documents, uncertain evidence or important business consequences may require a more capable model. Extracting a date, classifying a message or summarizing a short document may not.
The router evaluates the complexity, context and level of risk before selecting the appropriate model. If the request is ambiguous, the system can escalate it. If the task is simple and well defined, a smaller model can handle it faster and at a lower cost.
This does not mean choosing the cheapest model every time. It means avoiding the most expensive model when its additional intelligence creates no additional value. Good AI cost optimization begins by matching the capability of the model to the difficulty of the work.
Don’t pay twice for the same answer
Imagine working with an expert consultant who charges by the minute. If ten employees ask the same question, would you pay the consultant ten times to repeat the same answer? Probably not. Yet many AI systems do exactly that.
A semantic cache gives the system a form of controlled memory. It can recognise when two questions express the same intention, even when they use different words. “How do I change my password?” and “What are the steps to reset my access key?” may require the same approved answer.
Instead of calling the model again, the system can reuse a previous response when the context, permissions and source information have not changed. This reduces model usage and often improves response time, particularly for frequent internal questions.
But a cache is not a drawer where answers can be stored forever. Policies change, documents are updated and two similar questions may belong to users with different access rights. Every cached response therefore needs an expiration rule, a clear source and the same security controls as a newly generated answer. The saving only remains valuable if the answer remains trustworthy.
Send the Model Only What It Needs
The hidden cost: Every word sent to a model has a price. When an AI system is connected to company documents, the temptation is to send as much information as possible, just in case something might be useful.
But more context does not automatically produce a better answer. Imagine asking a question about annual leave and forcing someone to read an entire 500 page employment agreement before replying. The answer may be hidden somewhere inside, but the process is slow, expensive and unnecessarily confusing.
The right approach: A well designed retrieval layer identifies the passages that are genuinely relevant and sends only that evidence to the model. The most important saving often happens before the model is even called.
This reduces the number of tokens processed, shortens response time and gives irrelevant information fewer opportunities to influence the answer. The objective is not to deprive the model of context. It is to provide the smallest amount of reliable context required to complete the task correctly.
A model should not have to search through the entire library every time someone asks for one paragraph. Good architecture finds the right shelf first.
Does It Really Need to Happen Now?
The expensive assumption: Every AI request must be processed the moment it is created. In reality, the value of an answer does not always depend on receiving it within a fraction of a second.
Consider 5,000 old support tickets that need to be classified. Nobody is waiting in front of the screen for each individual result. Processing them as urgent requests only forces the architecture to pay for speed that the business does not need.
The architectural choice: Separate immediate interactions from work that can be queued. A customer assistant may require a fast response. Document indexing, historical analysis, report preparation or large classification jobs can often run in batches.
Batch processing groups compatible tasks and executes them when capacity is available or when the provider offers more favourable conditions. In a self hosted environment, it can also make better use of existing infrastructure instead of keeping expensive resources permanently ready for occasional peaks.
Making a user wait when an answer is urgent is poor design. Paying for an immediate answer when nobody is waiting is poor design too. AI cost optimization also means deciding which tasks genuinely deserve speed.
Smaller Models Can Carry Serious Work
The common mistake: Assuming that serious production work always requires the largest available model. For repetitive tasks with a limited scope, a smaller model may provide all the capability the business actually needs.
Open models can also be deployed on infrastructure controlled by the company. This may reduce licensing costs and dependence on an external provider, but it does not make the system free. Computing resources, monitoring, security, maintenance and model updates still have to be paid for and managed.
Quantization offers another option. It is similar to compressing a very large file so that it can fit on a more modest machine. By representing the model with less numerical precision, the system may require less memory and computing power.
But compression always deserves inspection. A lighter model can behave differently, and a small loss of accuracy may be harmless for one task but unacceptable for another. The result must therefore be tested against real business cases rather than judged only by its technical specifications.
The real calculation: Compare the total cost of producing a useful result, not only the price of running the model. A cheap model that creates errors, retries and manual corrections may become expensive. A smaller model that performs a clearly defined task reliably may be one of the most valuable components in the architecture.
AI Cost Optimization Is an Architecture Discipline
AI cost optimization is the architectural discipline of controlling how models, tokens, context, infrastructure and response times are used to create business value.
The principle is simple: Pay for additional capability only when that capability improves the result. Model routing avoids using excessive power for simple tasks. Semantic caching prevents the system from repeatedly solving the same problem. Precise retrieval limits unnecessary context. Batch processing reserves immediate execution for work that is genuinely urgent. Smaller models reduce consumption when the task is clearly defined. These practices also align with the FinOps Foundation’s guidance on AI and GenAI usage optimization.
None of these decisions is a shortcut. Each one requires evaluation, monitoring and a reliable way to escalate when the chosen option is no longer sufficient. The objective is not to produce the cheapest possible response. It is to control the cost of producing a response that remains useful, accurate and trustworthy.
A well designed AI system should also make its spending explainable. When the bill increases, the team should be able to identify which workloads, models and usage patterns caused it, and whether the value created increased with it. If cost cannot be connected to value, the architecture is not finished.
At Intech Heritage, we design AI systems that can move from demonstration to production without losing control of cost, security or quality. If an AI project is beginning to scale and its bill no longer tells a clear story, that is the right moment to examine the architecture.