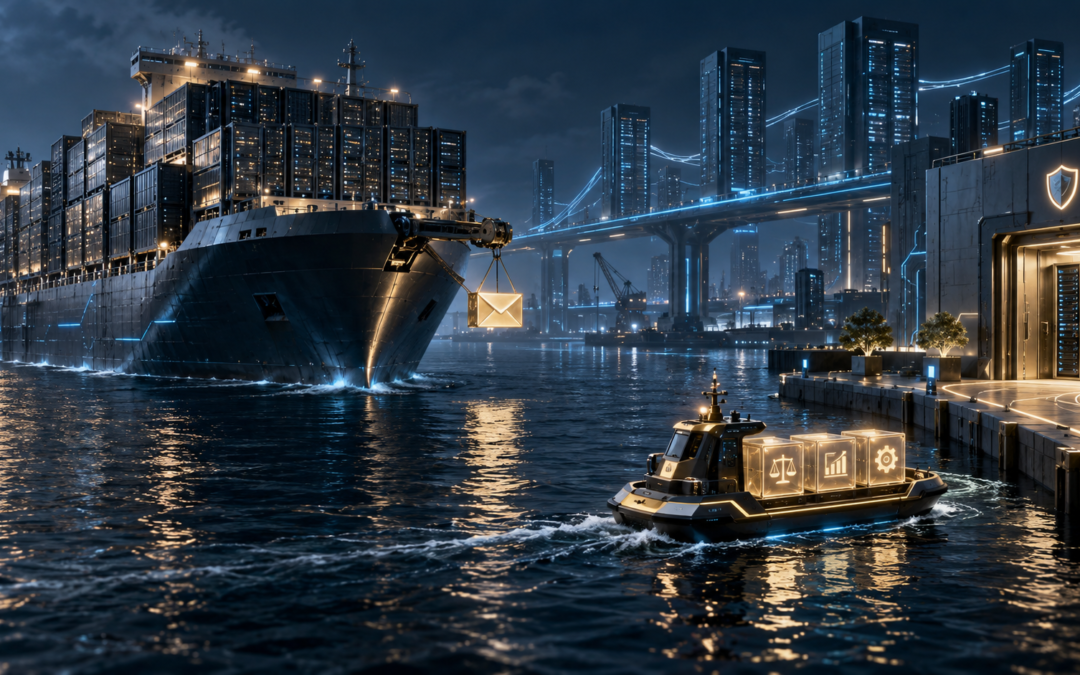
In the race for artificial intelligence, many companies are buying a cargo ship to deliver an envelope. They connect their simplest tasks to the largest models available, then wonder why the bill grows faster than the business value.
Small Language Models offer another path. They do not try to know everything. They are built to do a smaller number of things extremely well, with less infrastructure, lower latency and tighter control over sensitive data. In the right architecture, smaller does not mean weaker. It means sharper.
The Most Powerful Model Is Often the Wrong Model
For years, the conversation around AI has been dominated by size. More parameters, more data, more computing power. It sounds impressive, but architecture is not a bodybuilding contest.
Using a model with hundreds of billions of parameters to classify a support ticket or extract a few fields from an invoice is like opening an entire encyclopedia to check a telephone number. The answer may be inside, but the instrument is out of proportion to the question.
Small language models work more like specialised technical manuals. They cover less ground, but within that ground they can be faster, easier to control and far less expensive to operate.
The Right Size Is Defined by the Job
A Small Language Model, or SLM, is a language model with a relatively limited parameter count, designed or adapted to perform focused tasks with lower computing requirements than a general purpose Large Language Model. There is no magic number that turns a language model into a small one. Size only makes sense in relation to the work the model must perform, the infrastructure available and the speed the business actually needs.
A model that is compact enough for one company may still be unnecessarily heavy for another. The real question is not how many parameters it contains, but how much useful work each parameter is doing.
This changes the selection process completely. Instead of starting with a fashionable model and searching for somewhere to use it, we start with the task, the data and the operational constraints. Only then do we choose the engine.
Why Small Language Models Change the Economics of AI
AI architecture becomes very real when the invoice arrives. A model may be brilliant in a demonstration, but if every routine request requires expensive infrastructure, the system is carrying a grand piano up the stairs every time it needs to play one note.
Small Language Models change this equation in three places: computing power, response time and the cost of inference.
1. Less Computing Power, More Useful Work
Parameters are often described as the digital neurons of a model. The comparison is useful, but having more neurons does not automatically make every answer more valuable.
A general purpose model must carry an enormous amount of knowledge into every request. A specialised model carries less, but what it carries is closer to the task. It can therefore produce useful results with less memory, less processing power and a smaller technical footprint.
The objective is not to build the smallest model possible. It is to stop paying for intelligence the process never uses.
2. Latency Is a Business Cost
Waiting is an invisible tax. One slow response may seem harmless, but repeat it across thousands of requests, customer interactions or industrial operations and the delay begins to shape the entire system.
Small language models can often respond faster because they have less computational weight to move. For an assistant used by a plant operator, a legal team or a financial analyst, that difference is not cosmetic. It determines whether the tool becomes part of the workflow or another window people eventually stop opening.
3. Inference Is Where the Meter Keeps Running
Training a model attracts attention, but inference is where the operational bill lives. Every prompt consumes computing resources. Every automated process multiplies that consumption. At scale, a small inefficiency becomes an open tap.
Because Small Language Models require fewer resources, they can often run on more modest servers, within private infrastructure or closer to the systems that use them. This makes expenditure easier to predict and gives the architecture more room to grow without allowing every new use case to become a new financial surprise.
Where Small Language Models Become Strategically Stronger
The value of a smaller model does not stop at the infrastructure bill. In some environments, the ability to limit what a model knows, where it runs and how it behaves is more important than giving it access to the whole world.
This is particularly true in legal, financial and industrial systems, where a fluent answer is not necessarily a safe answer.
Privacy Begins With Architecture
Small language models can often run inside private infrastructure or closer to the data they need. This can reduce the amount of sensitive information sent to external services and give the company greater control over storage, access and monitoring.
That does not make the system compliant by magic. Hosting a model locally is not a security strategy on its own. But it creates a more controlled perimeter in which governance rules can be designed, observed and enforced.
The walls do not protect the building by themselves. They simply give the doors somewhere to exist.
In Regulated Work, Vocabulary Is Part of the Risk
A legal clause is not a casual sentence. A financial classification is not a guess dressed in confident language. In regulated environments, terminology carries obligations, consequences and sometimes considerable risk.
A general purpose model may understand the broad meaning of a document while still missing the precise language of a contract, a financial product or an internal procedure. A specialised Small Language Model can be trained and evaluated against that narrower vocabulary.
Its advantage is not that it knows more. It is that it has fewer places to wander.
Specialisation Makes Behaviour Easier to Control
When the model has a clearly defined role, its behaviour becomes easier to test. The company can build evaluation sets around real documents, known edge cases and the mistakes that matter most to the business.
This does not remove the need for human judgement. It gives that judgement a more predictable instrument.
A good specialist does not replace the person responsible for the decision. It removes some of the noise surrounding that decision.
Where Small Language Models Actually Earn Their Place
A Small Language Model earns its place where the road is narrow and the destination is clear. The task repeats often, the expected result can be measured and the model does not need to carry the entire internet on its back.
These are not the most spectacular use cases in a demonstration. They are often the ones that create the most durable value in production.
High Volume, Narrow Decisions
Classification, routing, summarisation and data extraction are natural candidates. A support ticket needs to reach the right team. An invoice needs a few fields extracted. A document needs to be assigned to the correct workflow.
None of these tasks requires a model to hold a philosophical debate. They require consistency, speed and a clear understanding of the company’s language.
When the same small decision occurs thousands of times, improving it by a few seconds or a few cents can have a measurable operational effect.
Specialised Assistants Close to the Work
Legal teams, financial analysts and operational departments often work with their own vocabulary, procedures and document structures. A focused assistant can help them search internal knowledge, summarise recurring documents, prepare an initial analysis or identify missing information.
The model should not make the final legal, financial or operational decision. Its role is to clear the desk before the expert sits down.
That distinction matters. The objective is not to automate responsibility. It is to give responsible people more time for the decisions that genuinely require them.
Systems That Cannot Wait for the Cloud
Some systems operate in factories, branches, vehicles or environments where connectivity is limited, expensive or simply too slow. In those situations, a compact model can run closer to the user or the machine generating the data.
The shorter distance can reduce latency and keep essential functions available when an external service is unreachable.
Sometimes the smartest AI architecture is not the one connected to the largest cloud. It is the one that continues working when the connection disappears.
The Question Is Not SLM or LLM
Architecture has a habit of creating false battles. Cloud or local. Build or buy. Small model or large model. In reality, the correct answer is often a combination governed by the task.
A Small Language Model is not a miniature replacement for every Large Language Model. Some problems require broad knowledge, complex reasoning or the ability to work across many different subjects. Giving those tasks to an overly limited model would be another form of bad architecture.
The same is true in the opposite direction. Routine classification, structured extraction and specialised internal assistance rarely need the largest engine available.
A carpenter does not spend the morning arguing whether a hammer is better than a screwdriver. The value lies in knowing which tool belongs in which hand.
A mature AI architecture can therefore use several models. Smaller models handle frequent, predictable and specialised work. Larger models are reserved for the situations that genuinely require their broader capabilities. A routing layer can decide which model receives each request according to complexity, sensitivity, latency and cost.
The objective is not to choose one model and defend it everywhere. It is to prevent every problem from being treated as if it were the same problem.
The Technical Decision Is Also a Financial Decision
Maturity in AI begins when a company stops asking which model is the most powerful and starts asking which system can perform the work reliably, safely and at the right cost.
Small Language Models are not valuable simply because they are smaller. They become valuable when their size matches the task, their behaviour can be tested and their operating cost remains proportionate to the value they create.
Every unnecessary parameter has a cost. Every avoidable call to an external service adds distance, dependency and uncertainty. None of these choices looks dramatic in a prototype. At scale, they become the architecture.
The strongest system is therefore not always the one with the largest engine. It is the one that knows when a large engine is necessary and when a smaller one will carry the business further.
Good architecture does not show off the size of the machine. It makes the machine run.