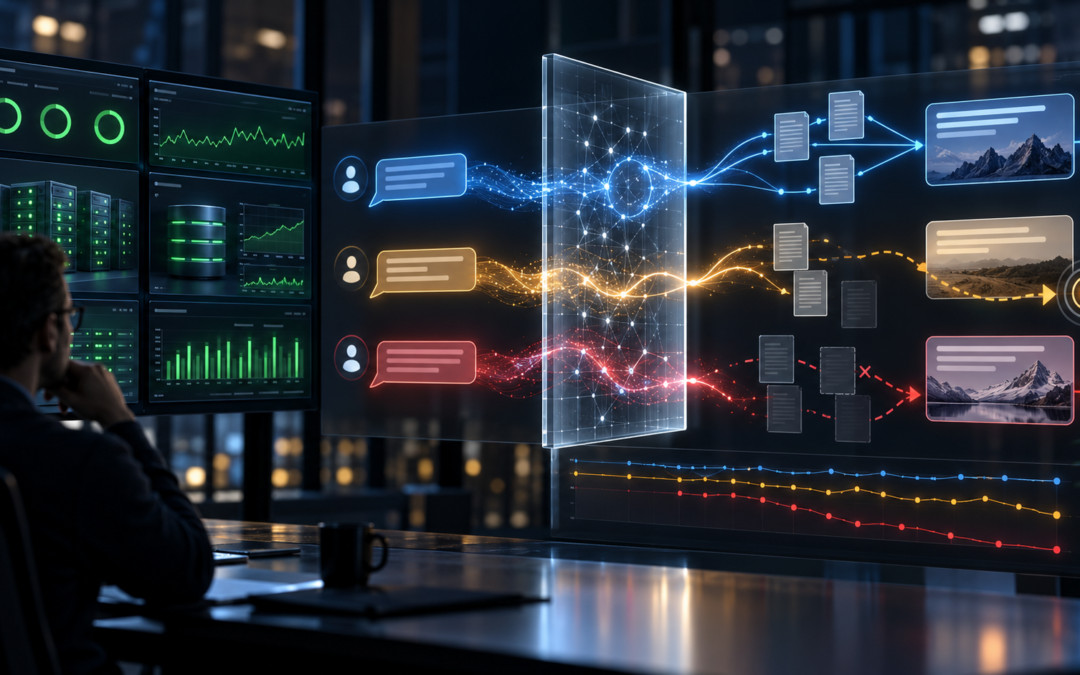
In traditional software, a green dashboard usually means the system is alive. With generative AI, that green light can be dangerously reassuring. The model may answer in milliseconds, return no error and still give the user something misleading, irrelevant or confidently invented. Semantic observability allows us to look beyond technical availability and ask the question that actually matters: is the system producing answers the business can trust and use?
The Green Dashboard Mirage: Why AI Availability Is Not Enough
For decades, operational readiness gave architects a clear signal: the servers were running, the database was responding and the system was available. The dashboard was green, so the job appeared to be done.
Generative AI breaks that comfort. A system can be technically healthy and still fail the business. It can respond in milliseconds, produce no error and deliver an answer that is false, irrelevant or stripped of the context needed to act. From the infrastructure’s point of view, nothing went wrong. From the user’s point of view, the system failed.
This is the blind spot semantic observability is designed to expose. It adds a new layer to our invisible engineering: evaluating whether an AI response deserves to be trusted, not merely whether the system managed to produce one.
What Semantic Observability Measures When AI Scales
Traditional observability watches the system’s body: uptime, latency, throughput and errors. Semantic observability listens to what the system is actually saying. It asks whether an answer is grounded in reliable information, relevant to the user’s intent and useful within the business process where it will be applied.
This distinction becomes critical at scale. A poor answer shown to one tester is an inconvenience. The same answer repeated across thousands of customer conversations becomes an operational risk. A production architecture therefore needs to evaluate three dimensions continuously:
Groundedness: Can the Answer Be Traced to Evidence?
Retrieval-augmented generation gives the model access to internal sources before it answers, but access alone does not guarantee fidelity. The model can retrieve the right document and still misread, combine or overstate what it contains.
Semantic evaluation should compare important claims with the retrieved evidence, flag unsupported statements and route uncertain responses towards correction, refusal or human review before they reach the user. The goal is to make uncertainty visible and controlled, even when that means the system should decline to answer.
Relevance: Did the System Solve the User’s Actual Problem?
A response can be factually correct and still be useless. The system may retrieve the right documentation, quote it accurately and completely miss what the user is trying to accomplish. This is one of the most expensive forms of failure because, on the surface, the answer still looks intelligent.
Relevance evaluation compares the user’s request, the retrieved context and the final answer. Depending on the risk, this can combine vector similarity, task-specific rules and secondary evaluator models. The objective is simple: detect when the AI has produced elegant text that occupies space but moves the user no closer to a decision or an action.
Drift: Is the System Still Reliable Over Time?
AI quality rarely collapses in one dramatic moment. More often, it erodes quietly. Users change the way they ask questions, source data evolves, business rules move, external APIs change and model updates can alter behaviour. The system remains online, but yesterday’s assumptions no longer hold.
Semantic observability turns that slow decay into a measurable signal. By tracking response quality across time, versions, user groups and task types, teams can detect degradation, investigate its cause and adjust prompts, retrieval, tools or model choices before the decline becomes visible to customers or expensive for the business.
The Business Case for Semantic Observability
Semantic observability is often treated as a quality-control layer. In production, it is also a financial control. Without it, an AI system becomes a polished black box: usage grows, costs accumulate and nobody can say with confidence whether its answers are creating value or quietly creating risk.
Resource and cost optimization: Quality data helps architects route each task to the least expensive model capable of meeting its requirements. A simple request may not need the largest model, while a complex or high-risk task may justify one. The decision is based on measured performance, not assumptions.
Business and reputational risk: Semantic signals can identify unsupported, inappropriate or policy-breaking answers before they spread across customer-facing channels. They do not eliminate risk, but they give teams evidence, thresholds and intervention points instead of leaving them to discover the problem through a complaint or a public incident.
Operational scalability: Scaling an AI system means scaling its mistakes as well as its successes. Without semantic quality metrics, more users simply create more opportunities for a plausible but harmful answer to be repeated. Measurement allows teams to expand within defined quality limits instead of multiplying uncertainty.
Invisible engineering does not end when the code reaches production. That is where it begins to prove its value. The model may sound confident, but the architecture around it must remain skeptical: observing its outputs, exposing uncertainty and distinguishing business value from tokens consumed with confidence.
Can You Prove That Your AI Is Creating Value?
An AI system earns its place in the business when its answers can be examined, measured and improved. Availability tells us the machine is running. Semantic observability tells us whether it is helping.
At Intech Heritage, we design the architecture around the model as carefully as the model itself: the evaluation loops, evidence, thresholds and controls that turn a convincing prototype into a dependable production system. When an AI answers quickly but nobody can explain whether those answers are useful, choosing a larger model only makes the blind spot more expensive.