We have normalized a dangerous lie about AI latency in business: if the answer is good enough, the user will forgive the wait.
In production, they rarely do. Friction destroys adoption. If an internal sales assistant or analytics tool leaves someone staring at a blank screen for eight seconds, that person eventually returns to the manual PDF or the familiar Excel sheet. It is not a lack of patience. A slow tool breaks the flow of daily work.
That is why AI latency is not merely a cosmetic UX problem. Once a system enters real operations, the infrastructure can matter as much as the language model itself. Data quality and model intelligence still matter, but neither will save a tool that feels unresponsive whenever someone needs it.
For leaders outside technical operations, latency is simply the time between clicking “send” and receiving the first sign of life from the system. Traditional software has trained us to expect that signal in milliseconds. Generative AI requires far more computation, and without the right architecture, those milliseconds can turn into painful seconds.
So how do we engineer AI systems that feel immediate and professional, even when the work behind the screen is complex? Five decisions make most of the difference.
Measure AI Latency Where Users Feel It: Time to First Token (TTFT)
The first measurement mistake is timing only how long the model takes to finish an answer. That number matters to engineering, but it does not explain what the user feels. The metric that shapes the experience is Time to First Token (TTFT): the delay between pressing “send” and seeing the first word appear.
Psychologically, there is an abyss between staring at a blank screen for five seconds and watching the answer begin to form after 800 milliseconds. In the first case, the user wonders whether the system is frozen. In the second, the system feels alive. The full response may still take several seconds, but the waiting has become reading. Reducing TTFT is one of the highest-leverage engineering decisions for perceived AI performance.
Streaming: The Illusion of Speed and Life
You have probably noticed that the best AI tools do not wait to deliver a finished block of text. They begin writing word by word. This is not an animation added to make the interface look sophisticated. It is a transmission technique called streaming.
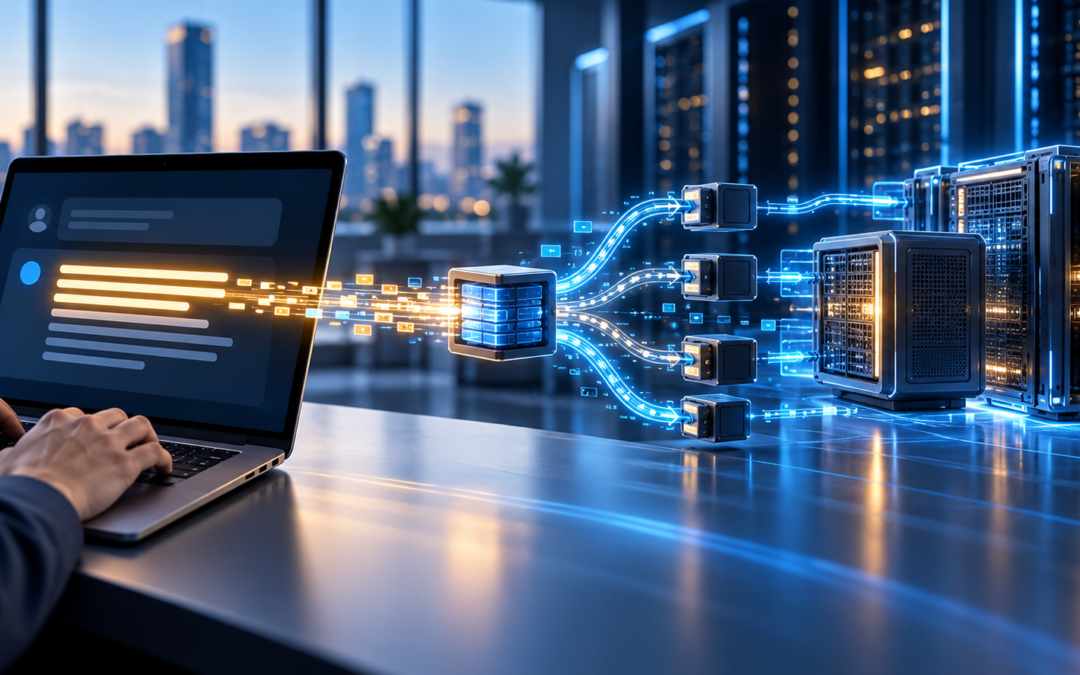
In a traditional REST integration, the server processes the request and returns the entire response at the end. That pattern is perfectly reasonable for many software operations, but dangerous for generative AI: the user sees nothing while the model works. Streaming changes the contract. Using Server-Sent Events, WebSockets, or an equivalent mechanism, the system sends each fragment as soon as it becomes available.
The result is psychological as much as technical. A passive wait becomes active reading. The user is already consuming the answer while the model is still composing its final sentence. Adding streaming to a legacy corporate system can be awkward, especially when proxies, gateways, and existing front ends were designed for complete responses. But it often marks the boundary between software that feels frozen and software that feels alive.
Semantic Caching: The Fastest Answer Is the One Not Calculated
Another invisible layer of AI latency engineering is preventing the system from repeating work it has already done. Suppose one employee asks, “What is our travel expense policy?” and the system produces a verified answer. Ten minutes later, another asks, “How do I submit my travel per diems?” The wording is different, but the intent may be close enough that calling the large model again would be wasteful.
This is where semantic caching earns its place. A traditional cache looks for identical requests. A semantic cache compares the meaning of the questions using embeddings and a similarity threshold. If the match is strong and the answer is still valid for that user, context, and permission level, the system can return the stored response in milliseconds.
That qualification matters. A fast wrong answer is still wrong. Policies change, permissions differ, and two similar questions are not always interchangeable. Used with expiration rules, access controls, and confidence thresholds, semantic caching can make frequent requests feel almost instant while reducing model calls and cloud costs.
Model Routing: Don’t Use a Sledgehammer to Crack a Nut
Not every request deserves the largest model in the room. A greeting, a date extraction, or a simple classification does not require the same reasoning capacity as analysing a contract or producing a multi-step business recommendation. Sending everything to the most capable model is like using a sledgehammer to crack a nut: it works, but slowly and expensively.
A mature architecture routes work according to its complexity. A small, fast model, or even a deterministic rule when AI is unnecessary, can identify the user’s intent, assess the level of risk, and select the appropriate execution path.
Complex reasoning, ambiguity, or a high-impact decision can be sent to a more capable model. Simple, repetitive, and well-bounded tasks can use a lightweight model that responds almost immediately.
Model routing is not about accepting lower quality. It is about matching the tool to the job. Done well, it reduces average AI latency and cost while reserving the strongest models for the moments that justify them. Done poorly, it creates unpredictable answers. The routing logic therefore needs clear criteria, fallbacks, and continuous evaluation.
Optimistic UI and Loading States
Eventually, engineering reaches a physical limit. If a complex request must search fifty documents, call several services, and assemble a grounded answer, no interface can make that work happen in zero time. This is where UX psychology becomes part of the architecture.
The screen must never feel abandoned. Clear status messages such as “Searching approved sources,” “Analysing documents,” or “Drafting the response” show that the system is progressing rather than frozen. In some workflows, an optimistic interface can also prepare the next step before every background operation has finished.
These signals do not make the model faster, but they reduce uncertainty. The user understands why the wait exists and what the system is doing with their request. W
hen latency cannot be eliminated, it must at least be explained.
The value of generative AI lies not only in what it says, but also in how and when the answer arrives. In business, a slow tool quickly becomes an abandoned tool. The model may attract attention during a demonstration, but the architecture determines whether the system survives daily work.
AI latency is therefore not a final optimization to schedule after launch. It is a design constraint that influences model choice, routing, caching, streaming, interfaces, infrastructure, and ultimately adoption. The invisible engineering around the model is what turns an impressive response into a dependable product.
Does your AI system perform well in demonstrations but feel slow, heavy, or unpredictable in daily operations? At Intech Heritage, we design the architecture that makes AI systems responsive, scalable, and ready for real business use.