A production RAG architecture can look deceptively simple in a proof of concept: connect a language model to a collection of documents, retrieve a few relevant passages and generate an answer. The difficulty begins when that same system meets real users, changing data, access rules and response time constraints.
That is where a common architectural mistake appears: treating RAG as a universal solution. Used without a clear reason, it can degrade the user experience, add latency and increase infrastructure costs without improving the answer.
Connecting an LLM to private data is not a simple API integration. It is a data engineering and distributed systems problem. The first question is not how to build RAG, but whether retrieval is the right answer to the problem.
The Rationality of Implementation: When does it provide real value?
RAG should not be treated as a patch for every limitation of a language model. It is a way to inject external context at the moment a response is generated. That distinction matters because RAG and fine-tuning do not solve the same problem. Fine-tuning can change how a model behaves or performs a specific task. RAG gives it access to knowledge that may be private, traceable or constantly changing.
In practice, retrieval becomes especially valuable in three situations:
- Data Sovereignty and Privacy: Some of a company’s most valuable knowledge is private by design: engineering manuals, medical records, legal contracts and internal procedures. RAG can retrieve this information when it is needed instead of trying to encode it into the model itself. But RAG does not create privacy on its own. Access rules must be enforced during retrieval so that each user sees only the information they are allowed to access.
- Information Volatility: Some knowledge loses value almost as soon as it is published. Stock levels, prices, regulations, market news and operating procedures can change too quickly for model training to keep pace. RAG can retrieve the latest available version at the moment of the question, provided that the source and the index are kept up to date. A model can only be as current as the information the system makes available to it.
- Traceability and Controlled Uncertainty: In a corporate environment, a plausible answer is not enough. The system should show where its answer came from and make the supporting document, page or passage available for verification. When reliable evidence cannot be retrieved, it should be designed to say that it does not know. RAG can reduce unsupported answers, but it cannot promise zero hallucinations. Trust comes from citations, evaluation and clear refusal rules, not from retrieval alone.
The Hidden Cost: When to avoid it?
The same discipline applies in the opposite direction. A RAG system is not more mature simply because it contains a vector database. Every retrieval step adds moving parts, and every moving part must earn its place. RAG is often the wrong choice in three situations:
- When every millisecond matters: A RAG request can involve query embedding, search, reranking, prompt construction and generation. Each step consumes time. In systems with very high request volumes or strict real-time constraints, retrieval may be too expensive unless the value of fresh context clearly justifies the delay. The real question is not whether RAG is fast or slow, but whether it fits the latency budget.
- When the model already has what the task needs: Some applications only require the model to summarize supplied text, classify content, rewrite a passage or support a creative task. In these cases, external retrieval may introduce irrelevant context, increase token consumption and make a simple operation unnecessarily complex.
- When the answer must be exact, not generated: An account balance, a stock level or the status of a transaction should come directly from the system that owns that information. An LLM may explain the result, but it should not approximate it. Vector search is not a substitute for a system of record.
Production RAG Architecture: Engineering Standards for Evaluation
Once the decision to use RAG is justified, implementation quality becomes the real issue. A demonstration can work with a handful of clean documents and carefully chosen questions. Production does not offer that comfort. The system must handle imperfect files, ambiguous requests, changing information and users who will ask questions nobody anticipated.
A reliable RAG architecture rests on four engineering pillars:
1. Data Quality and Chunking That Preserves Meaning
RAG cannot retrieve information that was extracted incorrectly or stripped of its context. That is why a practical AI data strategy should begin with the information that matters to the use case, not with the promise of perfect data. Headers, footers, tables, scanned pages and broken document structures can all distort the material before the model ever sees it.
Chunking is therefore not a mechanical exercise. Cutting every document after an arbitrary number of characters may separate a conclusion from its evidence or a question from its answer. But semantic chunking is not automatically better in every situation either. The strategy must be tested against real documents and real questions.
The right chunk is not the neatest one. It is the one that contains enough meaning to answer the question without burying the model in unnecessary context.
2. Retrieval That Handles Meaning and Precision
Vector search is powerful when the user’s wording differs from the source. It can recognize that two passages discuss the same idea even when they use different terms. But semantic similarity can struggle with exact reference numbers, product names, dates and technical codes.
Keyword search, metadata filters and reranking can complement vector retrieval when the use case requires both meaning and precision. This is where hybrid search often becomes valuable. It should not, however, be added automatically. The retrieval strategy must prove that it finds better evidence for the questions the system actually receives.
A fluent answer cannot repair the wrong evidence. If retrieval fails, generation starts from the wrong version of reality.
3. Latency and Cost as Architectural Constraints
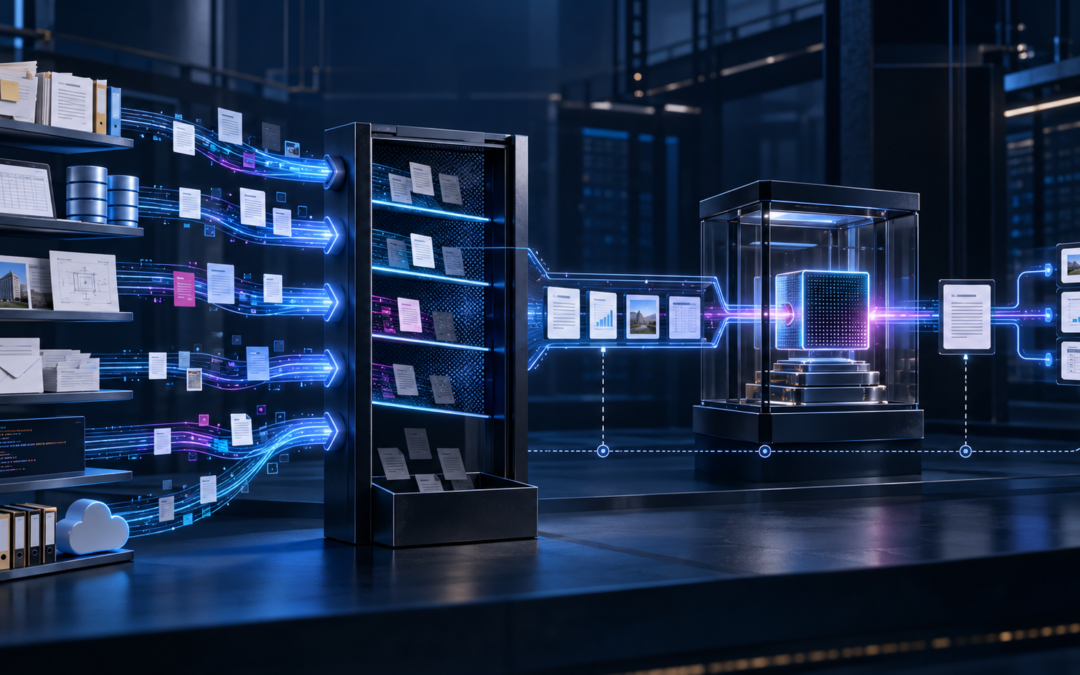
A production RAG architecture should separate the work performed during ingestion from the work performed when a user asks a question. Documents can be cleaned, divided and indexed before they are needed. At query time, the system still has to interpret the request, retrieve candidates, rerank them, construct the context and generate the answer.
As the collection grows, approximate nearest neighbor indexes such as HNSW can reduce search time. Caching can also prevent the system from repeating expensive work. Both require careful tuning because speed, memory consumption, retrieval quality and cost influence one another.
A fast answer is useless if it is wrong. A perfect answer is also useless if it arrives too late. The architecture must define an acceptable balance before production traffic defines it instead.
4. Evaluation of the Complete System
An LLM is probabilistic, but the way we test the system does not have to be improvised. A stable set of representative questions can be used to compare each version and detect regressions before deployment.
Evaluation should examine the complete chain: whether the correct passages were retrieved, whether the answer remained faithful to those passages, whether its citations support its claims, whether the system refused to answer when evidence was missing, and whether latency and cost stayed within acceptable limits.
Automated metrics such as faithfulness and relevance are useful, but they do not replace human review. They also cannot explain every failure on their own.
If we evaluate only the final answer, we cannot know whether the system failed to find the evidence or failed to use it correctly.
Artificial intelligence, applied correctly, is not magic. It is high-precision software engineering. A production RAG architecture does not become reliable because the model is powerful or the demonstration is convincing. It becomes reliable when the architecture knows what to retrieve, what to ignore, when to refuse and how to prove that an answer deserves to be trusted.
That is the real distance between a prototype and a production system. Robustness does not come from the model. It comes from the data architecture, the controls and the engineering discipline that support it.