RAG data engineering brings us back to one of computer science’s oldest warnings: garbage in, garbage out. Large language models did not make that warning obsolete. They made it more expensive to ignore.
When a Retrieval-Augmented Generation system begins producing disjointed answers, contradictory facts or confident replies that overlook documents we know exist, the model is usually the first suspect. Sometimes it deserves the blame. Often, the evidence reached it already damaged.
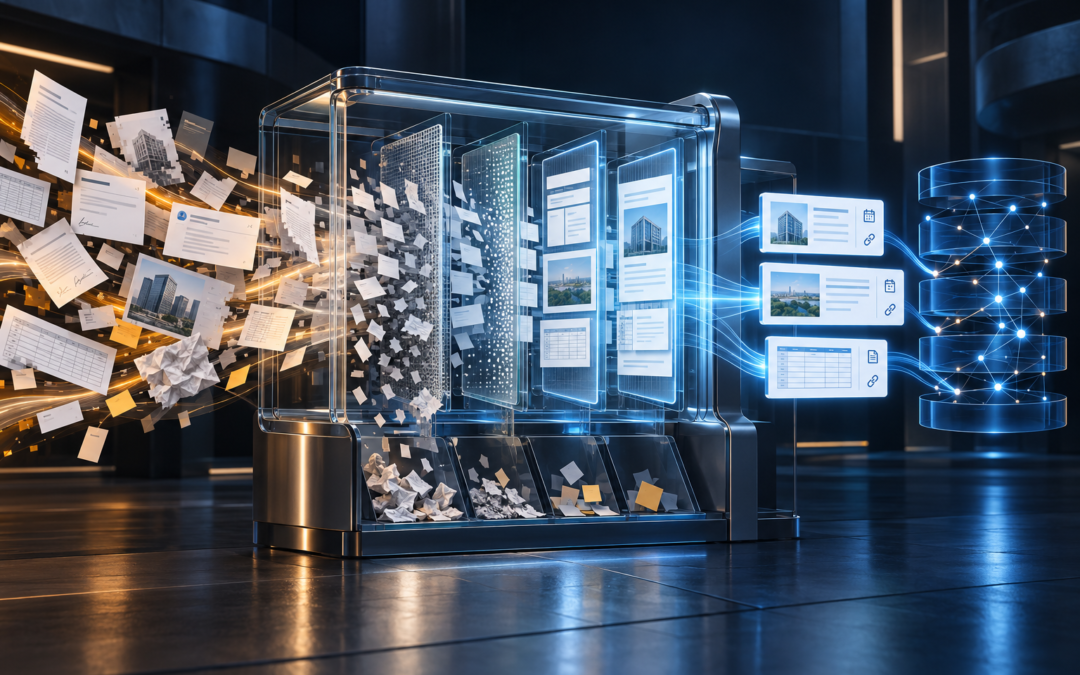
A corporate document is not clean information merely because a person can open it. PDFs carry repeated headers, broken tables, page numbers, watermarks and footnotes pulled out of place. Emails drag signatures and legal disclaimers through every conversation. Once those fragments are extracted and indexed without care, structural noise begins to look like knowledge.
Imagine handing a financial analyst a 100-page report in which the paragraphs have been shuffled, key figures are hidden behind watermarks and the same disclaimer interrupts every page. The analyst may still sound confident, but the material has already placed a ceiling on the quality of the conclusion. RAG works under the same constraint.
This is the invisible part of RAG data engineering. Before a vector database can retrieve useful evidence, the ingestion pipeline must preserve structure, context, dates and provenance. Some sources can be processed in batches. Others need continuous or event-driven updates. The correct rhythm follows how quickly the business information changes, not a fashionable promise of real time.
Think of that pipeline as a water treatment plant. Its job is not to make the model brilliant. It is to prevent contaminated evidence from reaching the tap. When this layer is neglected, the AI may appear to hallucinate when the architecture has simply given it a bad diet.
Four Data Hygiene Controls Before RAG Indexing
Reliable RAG data engineering begins before vectorization. The exact controls depend on the source, the business risk and the questions the system must answer, but four areas deserve particular attention: document structure, chunking, metadata and temporal context. None of them should be applied mechanically. Each one must be tested against real documents and real retrieval failures.
Visual Noise and Structural Contamination
Corporate documents are written for human eyes, not retrieval systems. We instinctively ignore a repeated header, a page number, a watermark or a disclaimer. The ingestion pipeline does not. It receives each of them as if it belonged to the argument.
If “Confidential | Page 12” lands in the middle of a sentence, the problem is not merely ugly formatting. The sentence has been cut, its semantic continuity has been weakened and the evidence has already been altered before the model sees it.
Cleaning therefore cannot mean blindly stripping text. Regular expressions can remove predictable patterns, while layout analysis and document parsers can identify headers, footers, tables and sections. But every rule must be tested against real documents, because an aggressive filter can delete the clause that matters. The objective is surgical: remove the scaffolding while preserving the evidence.
Chunking Without Cutting Through the Meaning
Chunking looks like a simple matter of size until the first retrieval failure. A model may accept a long context window, but a retrieval system still needs units that are small enough to find and complete enough to understand.
Cutting a document every 1,000 characters is like slicing a contract with a ruler. The dimensions are consistent, but the meaning is not. A clause can lose its exception, a question can be separated from its answer and a table can be detached from the heading that explains its figures. The database then stores fragments that are technically valid and intellectually incomplete.
A sound strategy follows the structure of the information: headings, paragraphs, tables, lists or changes of speaker. Semantic segmentation can help, but it is not automatically superior for every source. Overlap can protect context at a boundary, but too much overlap duplicates evidence, enlarges the index and fills the model’s context with repetition. The right chunk is not the one that satisfies a fashionable formula. It is the one that retrieves the evidence needed to answer real business questions.
Metadata Gives Every Fragment Coordinates
A fragment can be perfectly clean and still be almost useless if the system does not know where it came from. “Revenue rose by 5%” sounds precise, but it says very little without a year, a business unit, a region, a document version or even the name of the company concerned.
Vector similarity can find language that looks close to the question. It cannot determine by itself whether that fragment belongs to the correct period or business context. A request about 2023 may retrieve a remarkably similar report from 2019. The search engine has not necessarily failed. It was asked to navigate without coordinates.
Metadata gives each fragment those coordinates. During ingestion, the pipeline can attach information such as the source, publication date, department, document type, version and access permissions. Hybrid search can then combine exact filters, keyword matching and semantic similarity to narrow the field before the model receives the evidence.
But metadata is not magic. An incorrect date, an obsolete label or an overly restrictive filter can hide the very document the system needs. It improves retrieval only when its quality is governed and tested as carefully as the text itself.
Dates and Entities Need Memory, Not Reinvention
Natural language ages badly. Expressions such as “last month”, “yesterday” or “next year” are perfectly clear when a document is written and dangerously ambiguous when the same document is retrieved years later. A forecast written in 2022 about “next year” must not silently become a forecast about the present.
The pipeline should resolve temporal references only when it has reliable evidence, such as the document’s creation date, publication date or surrounding context. The normalized date should be stored alongside the original wording, not used to erase it. If the source date is uncertain, that uncertainty must remain visible rather than being replaced by invented precision.
The same discipline applies to names and acronyms. “IH”, “Intech Heritage” and a former legal name may refer to the same organization, but normalization should connect them to a canonical entity while preserving the term used in the source and its provenance.
This work may happen during batch ingestion, scheduled updates or event-driven processing. It does not have to occur in real time. The objective is not to rewrite history so that the document becomes easier for a machine to read. It is to give the machine enough memory to understand when, where and to whom the words belonged.
Data Hygiene Is Where RAG Earns Trust
The most impressive model cannot compensate indefinitely for evidence stripped of its structure, context and history. Data hygiene may be the least visible part of a RAG system, but it is where the system either earns the right to influence a decision or remains a convincing demonstration that speaks fluently and remembers badly.
A corporate AI architecture resembles a high-precision industrial process. The quality of the final product depends not only on the machinery, but also on the condition of the raw material entering the production line. A larger model cannot recover a clause deleted during extraction, identify a date that was never preserved or restore provenance that disappeared before indexing.
Investing in data hygiene does not eliminate risk or guarantee a return. It makes failures easier to detect, trace and correct. When a corporate assistant produces inconsistent answers despite having access to the right documents, replacing the model should not be the first reflex. Inspect its diet first: extraction, structure, chunking, metadata, dates, permissions and provenance.
A RAG system becomes valuable when users can trust not only the answer, but also the path the evidence followed before reaching it. That trust is built upstream, long before the prompt reaches the model.