Let’s begin with an exercise in technical honesty.
Today, building an AI assistant that answers questions about internal documentation is surprisingly easy. A junior developer can assemble a convincing demo in an afternoon with Python, an orchestration framework, and an API key. In the controlled calm of a boardroom, the assistant responds quickly, remembers the question from two minutes ago, and everyone leaves impressed.
Then Monday morning arrives.
Five hundred employees open the same application. Responses slow down. One user continues a conversation and the assistant behaves as if they have never met. Another request reaches the model with only part of the context it needs. Another session receives incomplete context. Memory consumption rises, retries multiply, and the polished demo begins to behave unpredictably.
The model has not suddenly become less intelligent. The architecture has reached the part the demonstration concealed: AI state management.
AI state management is the way an application stores, retrieves, limits, and protects the context required across requests. It is what allows a stateless language model to participate in a continuous conversation without tying that continuity to one server, one browser tab, or one fragile block of memory.
The Uncomfortable Truth: AI Doesn’t Care About You (Or Remember You)
Before fixing the architecture, we need to remove one of the most convincing illusions in conversational AI: the model is not actually carrying the conversation forward.
At the inference boundary, a large language model does not automatically remember the previous request. It receives the context supplied for that call, generates a response, and stops. Some platforms provide conversation threads or stored messages, but that memory is still managed somewhere outside the model itself.
Think of the model as the expert in Memento: brilliant, capable, and forced to reconstruct reality every time the scene begins again. It does not remember your name, your previous question, or the tone you established five minutes ago unless the application gives that information back to it.
This is why the backend must become the model’s external working memory. For every interaction, it assembles the user’s new message, the relevant conversation history, the session information and, when necessary, supporting business data.
If the user asks, “And what is the price?”, the sentence means almost nothing on its own. The answer depends on what “it” refers to, who is asking, what was discussed before and which information that person is allowed to see. The model can reason over that context, but the application must first preserve and deliver it.
The Local Memory Trap (Or Why Demos Fail)
The local memory trap begins with a solution that is perfectly reasonable at small scale. During a demo or proof of concept, the developer stores the conversation in a variable inside the web server: memory = [].
One user talks to one application process, the process remains alive, and the illusion holds. Nothing has moved yet.
Production changes the rules.
When the Next Message Reaches Another Server
An enterprise application rarely depends on a single web server. Requests are distributed across several instances so that the system can absorb traffic and continue operating when one instance fails.
If the first message from User A reaches Server 1, but the next one reaches Server 2, the second server may know nothing about the conversation. The user asks, “And what is the price?” The assistant replies, “What price are you talking about?”
Sticky sessions can keep one user attached to the same server and may be a reasonable trade-off for some limited workloads. But they do not make local memory durable. If that server restarts, fails, or is replaced during a deployment, the conversation can still disappear. They also make rebalancing traffic and scaling the application more difficult.
The durable solution is to keep the conversational state outside the web process, where every authorised application instance can retrieve it.
When Context Becomes a Growing Tax
Conversation history grows with every exchange. If the application sends the entire transcript back to the model each time, every new answer carries the weight of all the previous ones.
That weight has several forms. More input tokens increase the cost of the request. Larger prompts also increase AI latency because they take longer to transmit and process. Irrelevant details accumulate, making it harder for the model to identify what actually matters.
The user experiences a conversation. The infrastructure experiences a document that becomes longer every time someone speaks.
When the Context Window Reaches Its Limit
Every model has a maximum amount of context it can process in a single request. The size varies between models and will continue to change, but the architectural problem remains.
Without a context-management strategy, a long conversation may eventually be rejected, truncated, or stripped of information that the user still considers important. The system does not always collapse spectacularly. It may do something more dangerous: continue responding while quietly losing the thread.
This is why state management cannot be reduced to saving a transcript. The architecture must decide what to retain, where to store it, how long to keep it, who may retrieve it, and what can safely be forgotten.
Production Architecture: How AI State Management Works
Once we accept that the model does not own the conversation, the architecture becomes easier to reason about. State is an application responsibility.
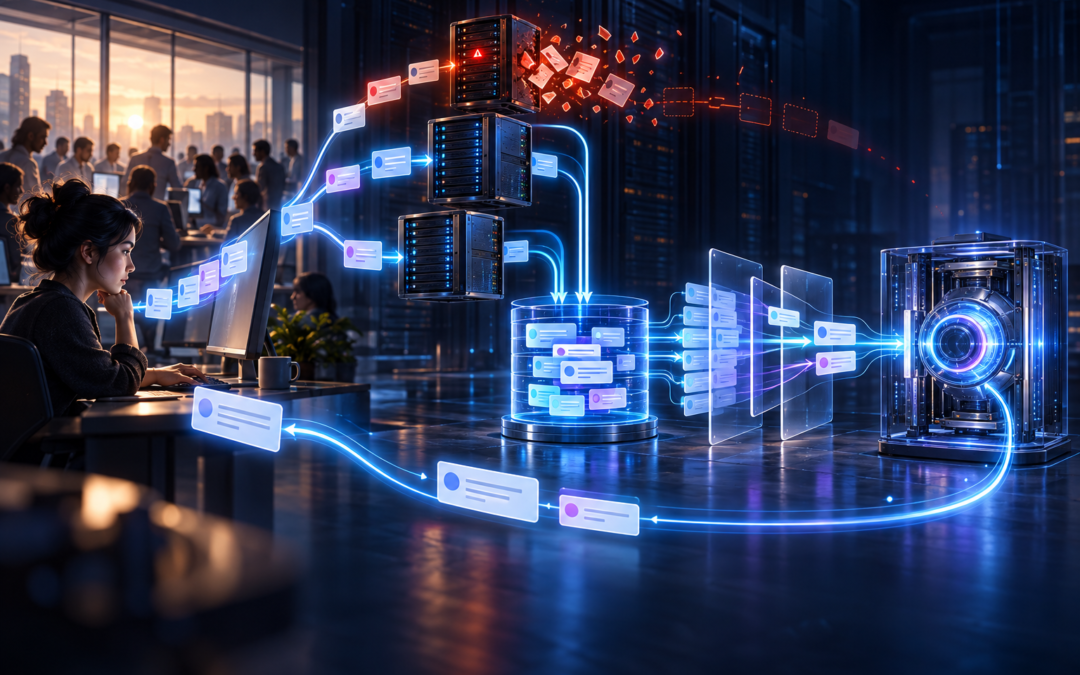
The user interface should not communicate directly with the language model. Every request should pass through a context-management and orchestration layer: the part of the application that identifies the user and session, retrieves the authorised state, selects the useful context, applies business rules, calls the model, and records what must survive the interaction.
Calling this layer an “intermediate brain” is tempting, but misleading. The model still performs the language reasoning. The orchestration layer decides what the model is allowed to know, what it needs for this request, and what the application should remember afterwards.
Before choosing Redis, DynamoDB, or any other technology, the architecture must define the properties that the state requires. Must it survive a server restart? How quickly must it be retrieved? Can two requests update it at the same time? How long should it exist? Which users and services may access it? Does it need an audit trail?
Those questions separate an architecture from a product catalogue. The database comes later.
Externalize the State Without Losing Control
In production, conversational state should not depend exclusively on the memory of a web server. Anything that must survive a restart, a deployment, or a request reaching another instance belongs in a shared state store.
For an active session that requires very fast access, Redis may be a good fit. DynamoDB or another durable database may be more appropriate when the state must persist for longer or operate across serverless components. The product name is not the architecture. The correct choice depends on durability, latency, consistency, retention, security, and cost.
When a message arrives, the orchestration layer validates the session, retrieves the latest authorised state, assembles the useful context, and calls the model. It then records the new exchange together with the metadata needed to manage its lifetime and access.
If two requests modify the same conversation simultaneously, the system also needs a concurrency strategy. Version checks, conditional writes, or carefully chosen locking mechanisms prevent one update from silently erasing another.
Externalising the state does not make the system infinitely scalable. The shared store still has capacity limits, consistency trade-offs, hot keys, security boundaries, and a bill of its own. What it does provide is independence: web servers can be added, replaced, or restarted without taking the conversation with them.
Decide What the System Should Remember
Storing the complete conversation does not mean sending the complete conversation to the model every time. The application may need a full record for continuity, auditing, or support, while the model only needs the parts that help it answer the current request.
Context management is similar to packing for a journey. You bring what the next stage requires, not the entire contents of your house.
The most recent exchanges can be kept in a sliding window, but the window should be based on the task and the available token budget, not an arbitrary number of messages. A debugging conversation may require several detailed turns. A simple request may need only the previous question.
Older exchanges can be compressed into a rolling summary. Important facts such as the user’s objective, selected product, permissions, or unresolved decisions can also be stored as structured session data instead of being buried inside a paragraph of generated text.
When an older part of the conversation becomes relevant again, semantic retrieval can locate candidate fragments from the conversation archive. This may use techniques similar to RAG, but it is not the same problem as retrieving evidence from a company knowledge base. Conversational memory has different sources, retention rules, permissions, and risks.
Summaries and retrieved fragments must also remain traceable. A generated summary can distort a detail, and a semantically similar message is not always the right one. The system should be able to return to the original exchange when accuracy matters.
Forgetting is not necessarily a failure. Human conversations also discard irrelevant detail. The failure is forgetting by accident, without knowing what was removed or why.
Conclusion: A Model Is Not a Production System
Artificial intelligence is fascinating because the model is the part we can see. We ask a question, words appear, and intelligence seems to live inside the screen.
But a production system is also built from everything that remains invisible: session identity, durable state, concurrency control, context selection, permissions, retention rules, monitoring, and recovery when something fails.
A stateless model can generate an excellent answer. It cannot decide which conversation must survive a deployment, prevent two simultaneous updates from overwriting each other, or determine whether one employee is allowed to retrieve another employee’s context. Those responsibilities belong to the architecture around it.
If an AI strategy begins and ends with choosing the model, it is still a castle built on sand. A more powerful model will not repair a lost session, recover an overwritten exchange, or explain why confidential context reached the wrong request.
AI state management is what turns isolated model calls into a continuous and controlled application. It forces the team to make explicit decisions about what the system remembers, where that memory lives, who owns it, how long it survives, and what happens when part of the infrastructure disappears.
Before asking which model to use, ask a less fashionable question: what must this system remember on Monday morning when 500 people arrive?
If the architecture cannot answer that question clearly, the demo is not yet a product.